Strix HaloAvailable
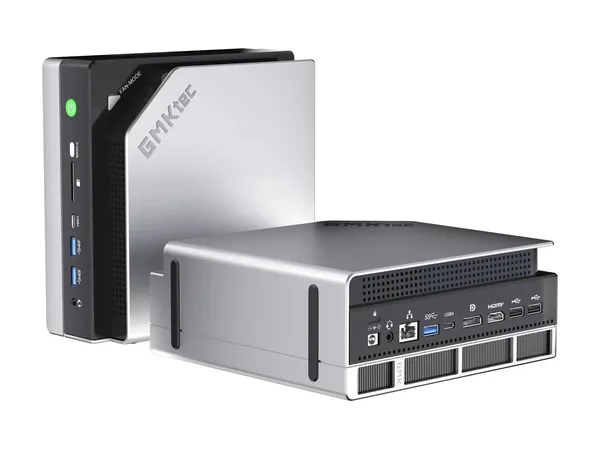
GMKtec EVO-X2
Ryzen AI Max+ 395, 64GB / 1TB
$2,200at GMKtec store
64 GB · 256 GB/s · ~48 GB usable
Check pricePlatform guide · AMD Strix Halo
Yes for big mixture-of-experts models, less so for big dense ones. Strix Halo (AMD Ryzen AI Max+ 395) mini PCs pair up to 128 GB of unified memory with 256 GB/s, starting at $2,200 (64 GB) and $3,500 for 128 GB. That memory holds 120B-class MoE models like Qwen3.5 122B-A10B at ~29 tok/s, but a dense Llama 3.3 70B crawls at ~5 tok/s. Prices & stock checked 2026-10-24. Prices change daily and some retailers block our checker, so always confirm on the store page.
| Model | Fit & est. speed |
|---|---|
| Qwen3.5 9B~7 GB at 4-bit, dense | Fits~37 tok/s |
| Gemma 4 12B~9 GB at 4-bit, dense | Fits~28 tok/s |
| GPT-OSS 20B~13 GB at 4-bit, 3.6B active | Fits~69 tok/s |
| Gemma 4 26B-A4B~18 GB at 4-bit, 3.8B active | Fits~61 tok/s |
| Qwen3.8 27B~19 GB at 4-bit, dense | Fits~12 tok/s |
| GLM-4.7-Flash 30B-A3B~21 GB at 4-bit, 3B active | Fits~72 tok/s |
| Gemma 4 31B~21 GB at 4-bit, dense | Fits~11 tok/s |
| Qwen3.6 35B-A3B~24 GB at 4-bit, 3B active | Fits~72 tok/s |
| Llama 3.3 70B~46 GB at 4-bit, dense | Fits~5 tok/s |
| Qwen3-Next 80B-A3B~52 GB at 4-bit, 3B active | Fits~72 tok/s |
| Llama 4 Scout 109B-A17B~71 GB at 4-bit, 17B active | Fits~18 tok/s |
| GPT-OSS 120B~67 GB at 4-bit, 5.1B active | Fits~55 tok/s |
| Nemotron 3 Super 120B-A12B~78 GB at 4-bit, 12B active | Fits~25 tok/s |
| Qwen3.5 122B-A10B~79 GB at 4-bit, 10B active | Fits~29 tok/s |
Estimated single-user decode at ~8K context on GMKtec EVO-X2 (~96 GB usable, 256 GB/s). How we estimate
| Hardware | Model / run | Measured tok/s | Our formula | Source |
|---|---|---|---|---|
| Strix Halo256 GB/s | Llama-2 7B Q4_0llama.cpp Vulkan tg128 | 52.7 | 53.4 | source |
| Strix Halo256 GB/s | Qwen3 8B Q4_K_Mllama.cpp Vulkan tg128 | 41.4 | 40.7 | source |
| Strix Halo256 GB/s | Mistral Small 24B Q4_K_Mllama.cpp Vulkan tg128 | 14.3 | 14.3 | source |
| Strix Halo256 GB/s | Llama 3.3 70B Q4_K_Mllama.cpp Vulkan tg128 | 4.8 | 4.8 | source |
| Strix Halo256 GB/s | Qwen3 30B-A3B Q4_K_Mllama.cpp Vulkan tg128 | 85.5 | 67.3 | source |
| Strix Halo256 GB/s | Qwen3 30B-A3B UD-Q4_K_XLllama.cpp Vulkan tg128 | 75.3 | 67.3 | source |
| Strix Halo256 GB/s | Qwen3-Coder-Next 80B-A3B Q4_K_Mllama.cpp Vulkan tg128 | 57.5 | 71.5 | source |
| Strix Halo256 GB/s | Llama 4 Scout UD-Q4_K_XLllama.cpp Vulkan tg128 | 20.2 | 18.0 | source |
| Strix Halo256 GB/s | gpt-oss-120b MXFP4llama.cpp ROCm tg128 | 47.5 | 54.6 | source |
| Strix Halo256 GB/s | Qwen3 235B-A22B IQ3_XSllama.cpp Vulkan tg128 | 18.1 | 20.2 | source |
| Strix Halo256 GB/s | Qwen3.6 35B-A3B Q4_K_MOllama/llama.cpp | 63.0 | 71.5 | source |
| Framework Desktop (Strix Halo)256 GB/s | Llama 3.1 70B Q4_K_MOllama (Geerling) | 5.0 | 4.8 | source |
Public llama.cpp / Ollama results we calibrate against. Full list: our estimates vs 52 real benchmarks.
| Machine | Price | Memory | Bandwidth | GPT-OSS 120B | Llama 3.3 70B |
|---|---|---|---|---|---|
| GMKtec EVO-X2Strix Halo | $3,500 | 128 GB | 256 GB/s | Fits~55 tok/s | Fits~5 tok/s |
| Lenovo ThinkStation PGXDGX Spark / GB10 | $5,859 | 128 GB | 273 GB/s | Fits~61 tok/s | Fits~5 tok/s |
| Mac Studio M5 UltraMac Studio | $5,499 | 96 GB | 1,200 GB/s | Tight fit~109 tok/s | Fits~23 tok/s |
Cheapest priced 128 GB Strix Halo, cheapest GB10 box and cheapest Mac Studio with comparable memory.
Ryzen AI Max+ 395, 64GB / 1TB
64 GB · 256 GB/s · ~48 GB usable
Check priceRyzen AI Max+ 395, 128GB / 1TB
128 GB · 256 GB/s · ~96 GB usable
Check priceRyzen AI Max+ 395, 128GB / 2TB
128 GB · 256 GB/s · ~96 GB usable
Check priceRyzen AI Max+ 395, 128GB / 2TB
128 GB · 256 GB/s · ~96 GB usable
Check priceRyzen AI Max+ 395, 128GB
128 GB · 256 GB/s · ~96 GB usable
Check priceFor MoE models, yes: with 128 GB (~96 GB usable by default) it runs GPT-OSS 120B at an estimated ~55 tok/s; a public ROCm run measured 47.5 tok/s. Dense 70B models run but only around 5 tok/s.
We count ~75% of RAM as usable by default (96 GB of 128 GB). The driver limit can be raised with tuning, so models just over the line may still load.
Similar bandwidth (256 vs 273 GB/s) and both come with 128 GB, but the cheapest 128 GB Strix Halo we track is $3,500 versus $5,859 for the cheapest GB10 box. The Spark gets more usable memory (~85%) and CUDA.
A Mac Studio M5 Ultra with 96 GB has 1,200 GB/s, so it's much faster per token, but it's $5,499.
64 GB (~48 GB usable) is a tight fit for Llama 3.3 70B and can't hold GPT-OSS 120B (~67 GB). Pick 128 GB if you want 100B+ MoE models.
One short email a week: what got cheaper, what's back in stock, and which new open models your machine can run. Unsubscribe anytime.