Mac StudioAvailable
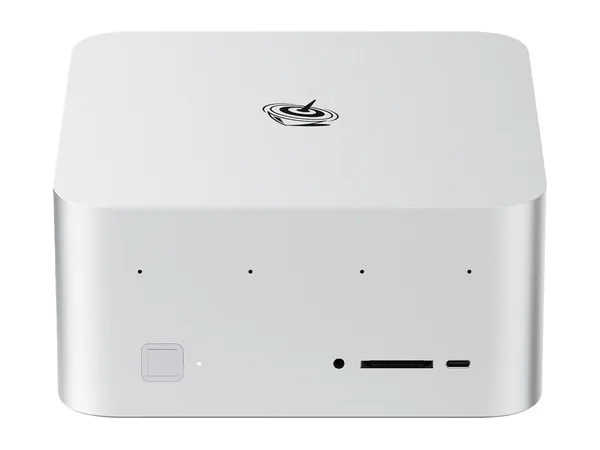
Mac Studio M5 Max
18-core CPU / 32-core GPU, 36GB
$2,499at Apple Store
36 GB · 460 GB/s
Check pricePlatform comparison
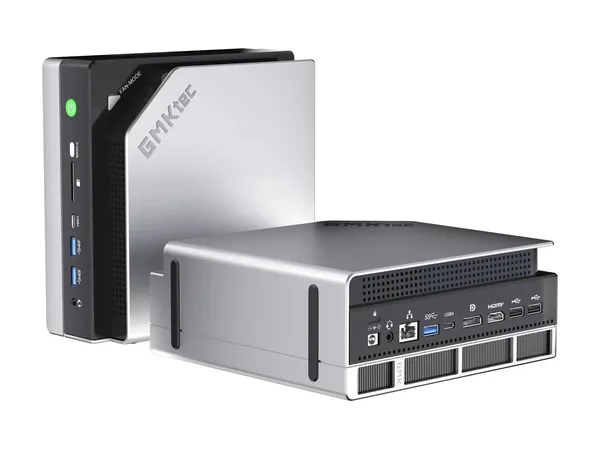
Mac Studio has more memory bandwidth (up to 1,200 GB/s vs 256 GB/s), so it generates tokens faster on the same model. Among priced configs, Strix Halo offers the most usable model memory (~96 GB vs ~72 GB). The cheapest Mac Studio we track is $2,499 (Mac Studio M5 Max, 36 GB); the cheapest Strix Halo is $2,200 (GMKtec EVO-X2, 64 GB). Prices & stock checked 2026-10-23. Prices change daily and some retailers block our checker, so always confirm on the store page.
| Apple Mac Studio (M5 Max / M5 Ultra) | Strix Halo mini PCs (Ryzen AI Max+ 395) | |
|---|---|---|
| Machines tracked | 4 | 5 |
| Price range | $2,499–$5,499 | $2,200–$4,349 |
| Memory options | 36 GB–256 GB | 64 GB–128 GB |
| Bandwidth | 460 GB/s–1,200 GB/s | 256 GB/s |
| Usable for models (est.) | ~75% of memory | ~75% of memory |
| Software | MLX / Metal | ROCm / Vulkan |
No current price for: Mac Studio M5 Ultra. It's left out of the price ranges.
| Model | Mac Studio | Strix Halo |
|---|---|---|
| Qwen3.5 9B | up to ~139 tok/sfrom $2,499 (Mac Studio M5 Max) | up to ~37 tok/sfrom $2,200 (GMKtec EVO-X2) |
| Gemma 4 12B | up to ~111 tok/sfrom $2,499 (Mac Studio M5 Max) | up to ~28 tok/sfrom $2,200 (GMKtec EVO-X2) |
| GPT-OSS 20B | up to ~119 tok/sfrom $2,499 (Mac Studio M5 Max) | up to ~69 tok/sfrom $2,200 (GMKtec EVO-X2) |
| Gemma 4 26B-A4B | up to ~114 tok/sfrom $2,499 (Mac Studio M5 Max) | up to ~61 tok/sfrom $2,200 (GMKtec EVO-X2) |
| Qwen3.8 27B | up to ~55 tok/sfrom $2,499 (Mac Studio M5 Max) | up to ~12 tok/sfrom $2,200 (GMKtec EVO-X2) |
| GLM-4.7-Flash 30B-A3B | up to ~120 tok/sfrom $2,499 (Mac Studio M5 Max) | up to ~72 tok/sfrom $2,200 (GMKtec EVO-X2) |
| Gemma 4 31B | up to ~49 tok/sfrom $2,499 (Mac Studio M5 Max) | up to ~11 tok/sfrom $2,200 (GMKtec EVO-X2) |
| Qwen3.6 35B-A3B | up to ~120 tok/sfrom $2,499 (Mac Studio M5 Max) | up to ~72 tok/sfrom $2,200 (GMKtec EVO-X2) |
| Llama 3.3 70B | up to ~23 tok/sfrom $5,499 (Mac Studio M5 Ultra) | up to ~5 tok/sfrom $2,200 (GMKtec EVO-X2) |
| Qwen3-Next 80B-A3B | up to ~120 tok/sfrom $5,499 (Mac Studio M5 Ultra) | up to ~72 tok/sfrom $3,449 (Framework Desktop DIY) |
| Llama 4 Scout 109B-A17B | up to ~60 tok/sfrom $5,499 (Mac Studio M5 Ultra) | up to ~18 tok/sfrom $3,449 (Framework Desktop DIY) |
| GPT-OSS 120B | up to ~109 tok/sfrom $5,499 (Mac Studio M5 Ultra) | up to ~55 tok/sfrom $3,449 (Framework Desktop DIY) |
| Nemotron 3 Super 120B-A12B | up to ~73 tok/sonly on a config with no current price | up to ~25 tok/sfrom $3,449 (Framework Desktop DIY) |
| Qwen3.5 122B-A10B | up to ~80 tok/sonly on a config with no current price | up to ~29 tok/sfrom $3,449 (Framework Desktop DIY) |
Fastest estimated decode across each platform's tracked configs, and the cheapest priced config that fits. How we estimate
18-core CPU / 32-core GPU, 36GB
36 GB · 460 GB/s
Check price18-core CPU / 40-core GPU, 48GB
48 GB · 614 GB/s
Check price30-core CPU / 64-core GPU, 96GB
96 GB · 1,200 GB/s
Check priceRyzen AI Max+ 395, 64GB / 1TB
64 GB · 256 GB/s
Check priceRyzen AI Max+ 395, 128GB
128 GB · 256 GB/s
Check priceRyzen AI Max+ 395, 128GB / 1TB
128 GB · 256 GB/s
Check priceRyzen AI Max+ 395, 128GB / 2TB
128 GB · 256 GB/s
Check priceRyzen AI Max+ 395, 128GB / 2TB
128 GB · 256 GB/s
Check priceMac Studio has more memory bandwidth (up to 1,200 GB/s vs 256 GB/s), so it generates tokens faster on the same model. Among priced configs, Strix Halo offers the most usable model memory (~96 GB vs ~72 GB).
The cheapest Mac Studio we track is $2,499 (Mac Studio M5 Max, 36 GB); the cheapest Strix Halo is $2,200 (GMKtec EVO-X2, 64 GB).
Decode speed scales with memory bandwidth, so Mac Studio is faster on any model that fits on both. Prompt processing depends on compute, where NVIDIA leads.
One short email a week: what got cheaper, what's back in stock, and which new open models your machine can run. Unsubscribe anytime.