Strix HaloAvailable
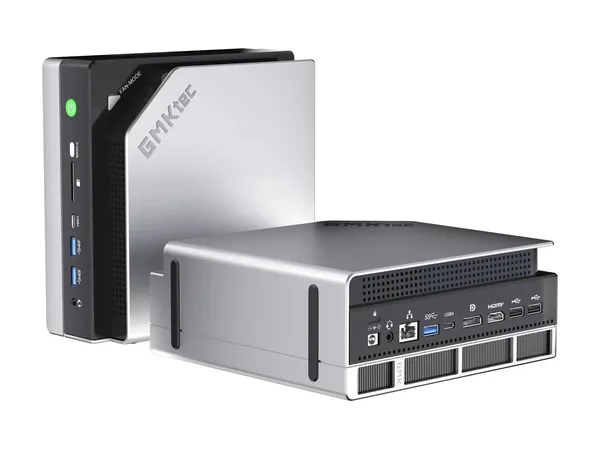
GMKtec EVO-X2
Ryzen AI Max+ 395, 64GB / 1TB
$2,200at GMKtec store
Cheapest that fits. Lowest price we've seen on any tracked rig that holds Llama 3.3 70B at 4-bit (46 of 48 GB usable).
Tight fit~5 tok/sQ4_K_M
Check priceMeta · 70B total / 70B active · dense
Llama 3.3 70B needs about 46 GB at Q4_K_M. 12 of the 17 priced rigs we track can hold it. Here's the cheapest, the best value and the fastest. Prices & stock checked 2026-10-23. Prices change daily and some retailers block our checker, so always confirm on the store page.
Ryzen AI Max+ 395, 64GB / 1TB
Cheapest that fits. Lowest price we've seen on any tracked rig that holds Llama 3.3 70B at 4-bit (46 of 48 GB usable).
30-core CPU / 64-core GPU, 96GB
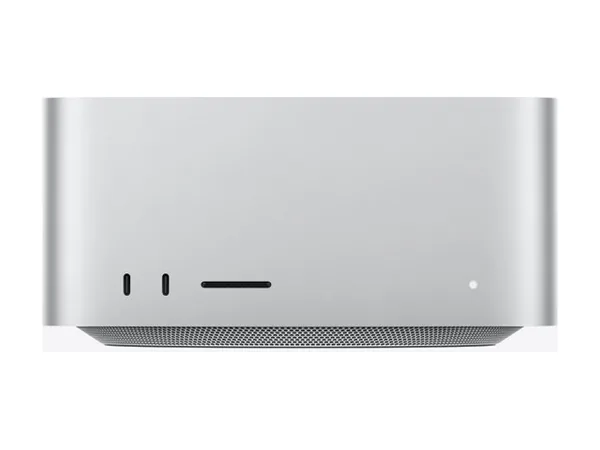
Best value. Lowest price per token/sec among complete systems where it fits comfortably: about $241 per tok/s at 4-bit.
96GB card
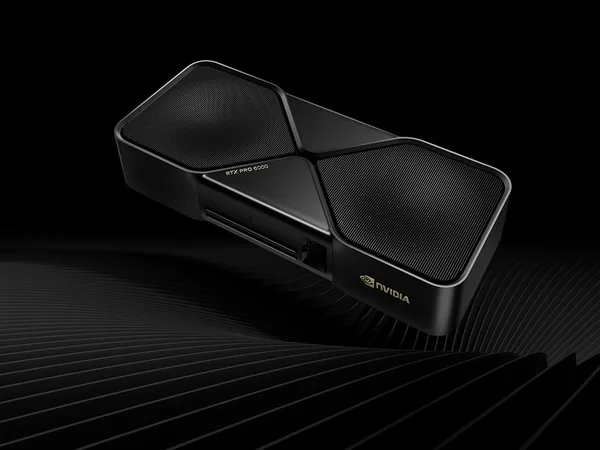
Fastest. Most memory bandwidth of the rigs that fit it (1,792 GB/s), so the quickest decode: ~34 tok/s at 4-bit.
Suggested quant: Q8_0 (~20 tok/s)
GPU price is card only: you still need a host PC.
Check priceUse Q4_K_M on most rigs: it needs ~46 GB. Q8_0 (~80 GB) is a bit more accurate and fits comfortably on 1 of these rigs, e.g. the PNY NVIDIA RTX PRO 6000 Blackwell.
| Machine | Price | 4-bit fit & speed | Suggested quant | $ per tok/s |
|---|---|---|---|---|
| GMKtec EVO-X2Strix Halo | $2,200 | Tight fit~5 tok/s | Q4_K_M | $456 |
| Framework Desktop DIYStrix Halo | $3,449 | Fits~5 tok/s | Q4_K_M | $715 |
| GMKtec EVO-X2Strix Halo | $3,500 | Fits~5 tok/s | Q4_K_M | $726 |
| Minisforum MS-S1 MaxStrix Halo | $3,919 | Fits~5 tok/s | Q4_K_M | $812 |
| Beelink GTR9 ProStrix Halo | $4,349 | Fits~5 tok/s | Q4_K_M | $902 |
| Mac Studio M5 UltraMac Studio | $5,499 | Fits~23 tok/s | Q4_K_M | $241 |
| Lenovo ThinkStation PGXDGX Spark / GB10 | $5,859 | Fits~5 tok/s | Q4_K_M | $1,183 |
| ASUS Ascent GX10DGX Spark / GB10 | $5,999 | Fits~5 tok/s | Q4_K_M | $1,211 |
| NVIDIA DGX SparkDGX Spark / GB10 | $6,950 | Fits~5 tok/s | Q4_K_M | $1,403 |
| HP ZGX Nano G1nDGX Spark / GB10 | $7,699 | Fits~5 tok/s | Q4_K_M | $1,554 |
| Gigabyte AI TOP ATOMDGX Spark / GB10 | $8,499 | Fits~5 tok/s | Q4_K_M | $1,716 |
| PNY NVIDIA RTX PRO 6000 BlackwellRTX PRO 6000 (card only, needs a host PC) | $17,899 | Fits~34 tok/s | Q8_0 | $529 |
Sorted by lowest price. Speeds are estimated single-user decode at ~8K context. Full fit table, including rigs that don't fit: Llama 3.3 70B memory requirements. How we estimate
About 46 GB at Q4_K_M and 80 GB at Q8_0, including runtime overhead and ~8K tokens of context for one user. Longer context needs more.
Of the rigs we track, the GMKtec EVO-X2 at $2,200, estimated ~5 tok/s at 4-bit. Prices checked 2026-10-23.
Q4_K_M is the default: about 46 GB. Q8_0 needs about 80 GB; use it only if you have the room and still get usable speed.
It has 70B active parameters per token, so speed is set by memory bandwidth: from ~5 tok/s on the slowest rig that fits to ~34 tok/s on the PNY NVIDIA RTX PRO 6000 Blackwell. Estimates, not benchmarks.
One short email a week: what got cheaper, what's back in stock, and which new open models your machine can run. Unsubscribe anytime.