Platform comparison
DGX Spark vs Strix Halo for local AI
DGX Spark has more memory bandwidth (up to 273 GB/s vs 256 GB/s), so it generates tokens faster on the same model. Among priced configs, DGX Spark offers the most usable model memory (~109 GB vs ~96 GB). The cheapest DGX Spark we track is $5,859 (Lenovo ThinkStation PGX, 128 GB); the cheapest Strix Halo is $2,200 (GMKtec EVO-X2, 64 GB). DGX Spark boxes run CUDA, which most tools support first, and process long prompts faster than Macs or Strix Halo. Prices & stock checked 2026-10-23. Prices change daily and some retailers block our checker, so always confirm on the store page.
At a glance
| DGX Spark and GB10 boxes (NVIDIA, ASUS, Lenovo, HP, Gigabyte) | Strix Halo mini PCs (Ryzen AI Max+ 395) | |
|---|---|---|
| Machines tracked | 5 | 5 |
| Price range | $5,859–$8,499 | $2,200–$4,349 |
| Memory options | 128 GB | 64 GB–128 GB |
| Bandwidth | 273 GB/s | 256 GB/s |
| Usable for models (est.) | ~85% of memory | ~75% of memory |
| Software | CUDA | ROCm / Vulkan |
Model by model (4-bit)
| Model | DGX Spark | Strix Halo |
|---|---|---|
| Qwen3.5 9B | up to ~39 tok/sfrom $5,859 (Lenovo ThinkStation PGX) | up to ~37 tok/sfrom $2,200 (GMKtec EVO-X2) |
| Gemma 4 12B | up to ~29 tok/sfrom $5,859 (Lenovo ThinkStation PGX) | up to ~28 tok/sfrom $2,200 (GMKtec EVO-X2) |
| GPT-OSS 20B | up to ~80 tok/sfrom $5,859 (Lenovo ThinkStation PGX) | up to ~69 tok/sfrom $2,200 (GMKtec EVO-X2) |
| Gemma 4 26B-A4B | up to ~70 tok/sfrom $5,859 (Lenovo ThinkStation PGX) | up to ~61 tok/sfrom $2,200 (GMKtec EVO-X2) |
| Qwen3.8 27B | up to ~13 tok/sfrom $5,859 (Lenovo ThinkStation PGX) | up to ~12 tok/sfrom $2,200 (GMKtec EVO-X2) |
| GLM-4.7-Flash 30B-A3B | up to ~83 tok/sfrom $5,859 (Lenovo ThinkStation PGX) | up to ~72 tok/sfrom $2,200 (GMKtec EVO-X2) |
| Gemma 4 31B | up to ~11 tok/sfrom $5,859 (Lenovo ThinkStation PGX) | up to ~11 tok/sfrom $2,200 (GMKtec EVO-X2) |
| Qwen3.6 35B-A3B | up to ~83 tok/sfrom $5,859 (Lenovo ThinkStation PGX) | up to ~72 tok/sfrom $2,200 (GMKtec EVO-X2) |
| Llama 3.3 70B | up to ~5 tok/sfrom $5,859 (Lenovo ThinkStation PGX) | up to ~5 tok/sfrom $2,200 (GMKtec EVO-X2) |
| Qwen3-Next 80B-A3B | up to ~83 tok/sfrom $5,859 (Lenovo ThinkStation PGX) | up to ~72 tok/sfrom $3,449 (Framework Desktop DIY) |
| Llama 4 Scout 109B-A17B | up to ~19 tok/sfrom $5,859 (Lenovo ThinkStation PGX) | up to ~18 tok/sfrom $3,449 (Framework Desktop DIY) |
| GPT-OSS 120B | up to ~61 tok/sfrom $5,859 (Lenovo ThinkStation PGX) | up to ~55 tok/sfrom $3,449 (Framework Desktop DIY) |
| Nemotron 3 Super 120B-A12B | up to ~26 tok/sfrom $5,859 (Lenovo ThinkStation PGX) | up to ~25 tok/sfrom $3,449 (Framework Desktop DIY) |
| Qwen3.5 122B-A10B | up to ~31 tok/sfrom $5,859 (Lenovo ThinkStation PGX) | up to ~29 tok/sfrom $3,449 (Framework Desktop DIY) |
Fastest estimated decode across each platform's tracked configs, and the cheapest priced config that fits. How we estimate
DGX Spark configs we track
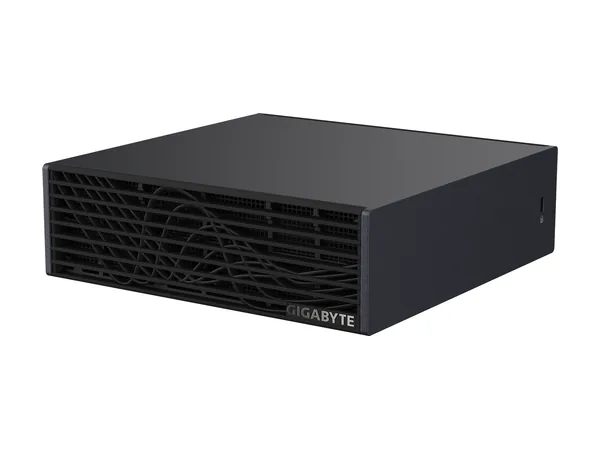
NVIDIA DGX Spark
Founders Edition, 4TB
128 GB · 273 GB/s
Check price
Strix Halo configs we track
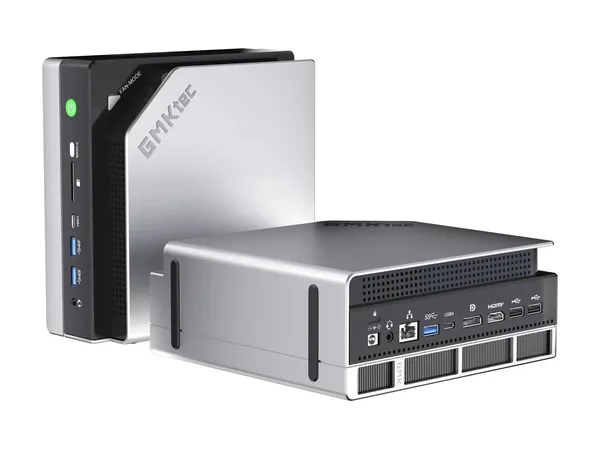
GMKtec EVO-X2
Ryzen AI Max+ 395, 64GB / 1TB
64 GB · 256 GB/s
Check price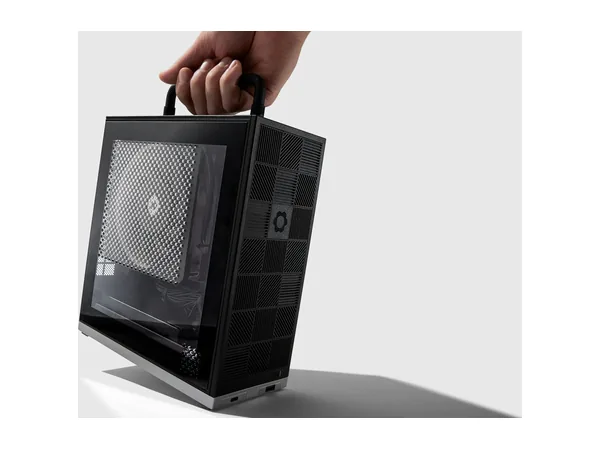
Framework Desktop DIY
Ryzen AI Max+ 395, 128GB
128 GB · 256 GB/s
Check priceGMKtec EVO-X2
Ryzen AI Max+ 395, 128GB / 1TB
128 GB · 256 GB/s
Check price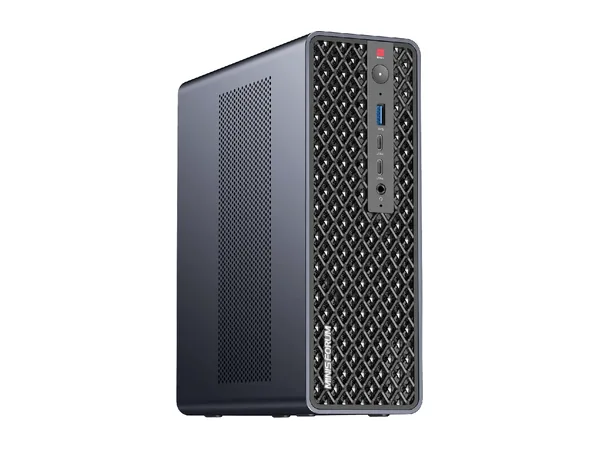
Minisforum MS-S1 Max
Ryzen AI Max+ 395, 128GB / 2TB
128 GB · 256 GB/s
Check price
Beelink GTR9 Pro
Ryzen AI Max+ 395, 128GB / 2TB
128 GB · 256 GB/s
Check priceFAQ
Is DGX Spark or Strix Halo better for local LLMs?
DGX Spark has more memory bandwidth (up to 273 GB/s vs 256 GB/s), so it generates tokens faster on the same model. Among priced configs, DGX Spark offers the most usable model memory (~109 GB vs ~96 GB).
Which is cheaper, DGX Spark or Strix Halo?
The cheapest DGX Spark we track is $5,859 (Lenovo ThinkStation PGX, 128 GB); the cheapest Strix Halo is $2,200 (GMKtec EVO-X2, 64 GB).
Which is faster for big MoE models?
Decode speed scales with memory bandwidth, so DGX Spark is faster on any model that fits on both. Prompt processing depends on compute, where NVIDIA leads.