Framework Desktop DIY vs GMKtec EVO-X2 for local AI
GMKtec EVO-X2 should generate tokens faster (more memory bandwidth). Both fit the same model sizes. GMKtec EVO-X2 is cheaper right now by $1,339.
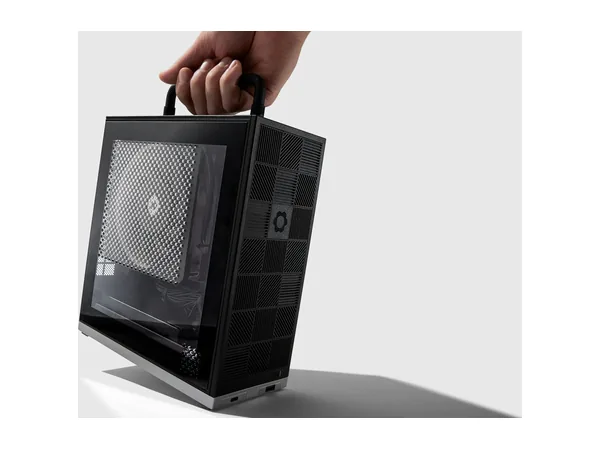
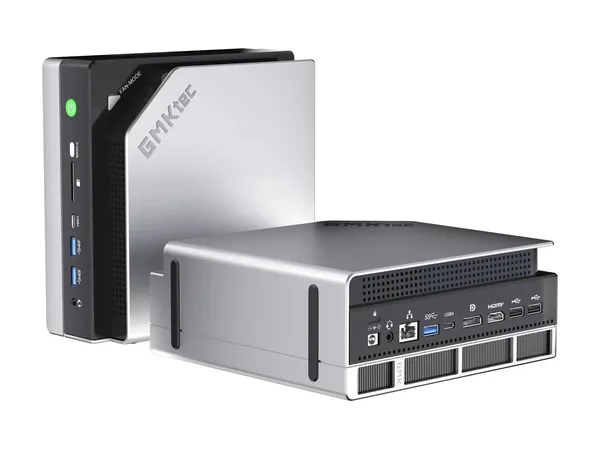
Specs
| Framework Desktop DIY | GMKtec EVO-X2 | |
|---|---|---|
| Stock | Out of stock | Available |
| Lowest price | $4,839 | $3,500 |
| Memory | 128 GB LPDDR5x unified | 128 GB LPDDR5X-8000 unified |
| Usable for models (est.) | ~96 GB | ~96 GB |
| Bandwidth | 256 GB/s | 256 GB/s |
| Software | ROCm / Vulkan | ROCm / Vulkan |
| Price per GB | $37.80 | $27.34 |
Model by model (4-bit)
| Model | Framework Desktop DIY | GMKtec EVO-X2 |
|---|---|---|
| Qwen3.5 9B | Fits~28 tok/s | Fits~28 tok/s |
| Gemma 4 12B | Fits~21 tok/s | Fits~21 tok/s |
| GPT-OSS 20B | Fits~80 tok/s | Fits~80 tok/s |
| Gemma 4 26B-A4B | Fits~67 tok/s | Fits~67 tok/s |
| Qwen3.8 27B | Fits~9 tok/s | Fits~9 tok/s |
| GLM-4.7-Flash 30B-A3B | Fits~84 tok/s | Fits~84 tok/s |
| Gemma 4 31B | Fits~8 tok/s | Fits~8 tok/s |
| Qwen3.6 35B-A3B | Fits~84 tok/s | Fits~84 tok/s |
| Llama 3.3 70B | Fits~4 tok/s | Fits~4 tok/s |
| Qwen3-Next 80B-A3B | Fits~84 tok/s | Fits~84 tok/s |
| Llama 4 Scout 109B-A17B | Fits~15 tok/s | Fits~15 tok/s |
| GPT-OSS 120B | Fits~57 tok/s | Fits~57 tok/s |
| Nemotron 3 Super 120B-A12B | Fits~21 tok/s | Fits~21 tok/s |
| Qwen3.5 122B-A10B | Fits~25 tok/s | Fits~25 tok/s |
| Qwen3 235B-A22B | Won't fit | Won't fit |
| Muse Spark Open 816B-A42B | Won't fit | Won't fit |