Mac miniAvailable
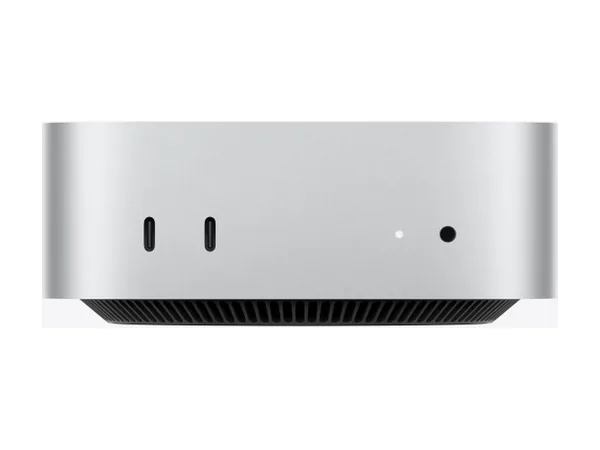
Mac mini M5 Pro
15-core CPU / 16-core GPU, 24GB
$1,699at Apple Store
24 GB · 307 GB/s · ~17 GB usable
Check priceMemory guide · RAM & VRAM
Rule of thumb: at 4-bit a model needs about 0.6 GB per billion parameters plus a little for context, and 8-bit (Q8_0) needs about 1.7× as much. So GPT-OSS 20B needs ~13 GB, Llama 3.3 70B ~46 GB, GPT-OSS 120B ~67 GB and Qwen3 235B-A22B ~151 GB. Memory decides whether a model runs; memory bandwidth decides how fast. Below: every model we track, what it needs, and the cheapest priced rig that holds it. Prices & stock checked 2026-10-24. Prices change daily and some retailers block our checker, so always confirm on the store page.
| Model | 4-bit | 8-bit (Q8_0) | Cheapest tracked rig that fits (4-bit) |
|---|---|---|---|
| Qwen3.5 9B9B total, dense | ~7 GBQ4_K_M | ~12 GB | Mac mini M5 Pro$1,699 · ~48 tok/s |
| Gemma 4 12B12B total, dense | ~9 GBQ4_K_M | ~15 GB | Mac mini M5 Pro$1,699 · ~36 tok/s |
| GPT-OSS 20B21B total, 3.6B active (MoE) | ~13 GBMXFP4 (native) | ~25 GB | Mac mini M5 Pro$1,699 · ~82 tok/s |
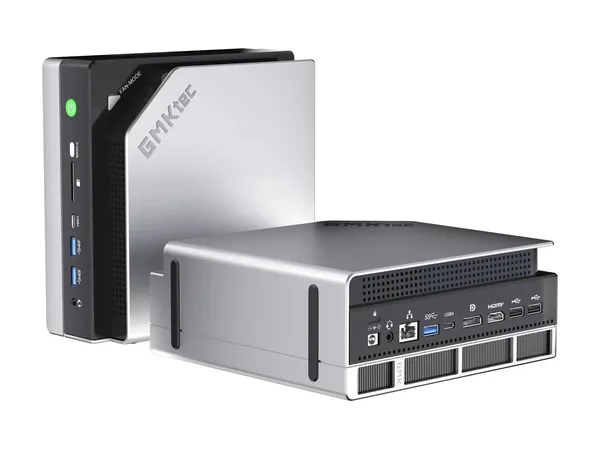
| Gemma 4 26B-A4B25.2B total, 3.8B active (MoE) | ~18 GBQ4_K_M | ~30 GB | GMKtec EVO-X2$2,200 · ~61 tok/s |
| Qwen3.8 27B27B total, dense | ~19 GBQ4_K_M | ~32 GB | GMKtec EVO-X2$2,200 · ~12 tok/s |
| GLM-4.7-Flash 30B-A3B30B total, 3B active (MoE) | ~21 GBQ4_K_M | ~35 GB | GMKtec EVO-X2$2,200 · ~72 tok/s |
| Gemma 4 31B31B total, dense | ~21 GBQ4_K_M | ~36 GB | GMKtec EVO-X2$2,200 · ~11 tok/s |
| Qwen3.6 35B-A3B35B total, 3B active (MoE) | ~24 GBQ4_K_M | ~41 GB | GMKtec EVO-X2$2,200 · ~72 tok/s |
| Llama 3.3 70B70B total, dense | ~46 GBQ4_K_M | ~80 GB | GMKtec EVO-X2$2,200 · ~5 tok/s |
| Qwen3-Next 80B-A3B80B total, 3B active (MoE) | ~52 GBQ4_K_M | ~91 GB | GMKtec EVO-X2$3,500 · ~72 tok/s |
| Llama 4 Scout 109B-A17B109B total, 17B active (MoE) | ~71 GBQ4_K_M | ~123 GB | GMKtec EVO-X2$3,500 · ~18 tok/s |
| GPT-OSS 120B117B total, 5.1B active (MoE) | ~67 GBMXFP4 (native) | ~132 GB | GMKtec EVO-X2$3,500 · ~55 tok/s |
| Nemotron 3 Super 120B-A12B120B total, 12B active (MoE) | ~78 GBQ4_K_M | ~135 GB | GMKtec EVO-X2$3,500 · ~25 tok/s |
| Qwen3.5 122B-A10B122B total, 10B active (MoE) | ~79 GBQ4_K_M | ~138 GB | GMKtec EVO-X2$3,500 · ~29 tok/s |
| Qwen3 235B-A22B235B total, 22B active (MoE) | ~151 GBQ4_K_M | ~264 GB | No priced rig we track |
| Muse Spark Open 816B-A42B816B total, 42B active (MoE) | ~521 GBQ4_K_M | ~912 GB | No priced rig we track |
Memory = weights + 1.5 GB + 5% of weights (~8K context, one user); weights = parameters × bits per weight ÷ 8 (Q4_K_M 4.85 bpw, Q8_0 8.5 bpw). Speeds are our estimates. How we estimate
| Memory | Biggest model that fits | Biggest dense model | Models that fit |
|---|---|---|---|
| 8GB VRAM~7 GB usable | Qwen3.5 9B | Qwen3.5 9B | 1 of 16 |
| 12GB VRAM~11 GB usable | Gemma 4 12B | Gemma 4 12B | 2 of 16 |
| 16GB VRAM~15 GB usable | GPT-OSS 20B | Gemma 4 12B | 3 of 16 |
| 24GB VRAM~22 GB usable | Gemma 4 31B | Gemma 4 31B | 7 of 16 |
| 32GB VRAM~30 GB usable | Qwen3.6 35B-A3B | Gemma 4 31B | 8 of 16 |
| 64GB unified memory~48 GB usable | Llama 3.3 70B | Llama 3.3 70B | 9 of 16 |
| 96GB unified memory~72 GB usable | GPT-OSS 120B | Llama 3.3 70B | 12 of 16 |
| 128GB unified memory~96 GB usable | Qwen3.5 122B-A10B | Llama 3.3 70B | 14 of 16 |
Generic sizes: GPU VRAM counted at 93% usable, unified memory (Mac, Strix Halo) at 75%. DGX Spark boxes get ~85%.
15-core CPU / 16-core GPU, 24GB
24 GB · 307 GB/s · ~17 GB usable
Check priceRyzen AI Max+ 395, 64GB / 1TB
64 GB · 256 GB/s · ~48 GB usable
Check priceRyzen AI Max+ 395, 128GB / 1TB
128 GB · 256 GB/s · ~96 GB usable
Check priceThe cheapest priced rig that fits each model above, without repeats.
At 4-bit (Q4_K_M), roughly 0.6 GB per billion parameters plus ~1.5 GB and 5% for ~8K context: ~7 GB for a 9B model, ~19 GB for 27B, ~46 GB for 70B. GPUs leave ~93% of VRAM usable.
About 46 GB at 4-bit and 80 GB at 8-bit. On a Mac or Strix Halo only about 75% of RAM is GPU-usable by default, so 64 GB is a tight fit at 4-bit and 96–128 GB is comfortable.
About 151 GB at 4-bit and 264 GB at 8-bit. Mixture-of-experts models still need memory for all their weights, even though only 22B are read per token. None of the priced rigs we track holds it at 4-bit right now.
No, it needs memory for every parameter, but it runs faster because each token only reads the active ones. GPT-OSS 120B needs ~67 GB but reads only 5.1B parameters per token.
Use a smaller quant (Q3 or lower costs quality), a smaller model, or offload layers to system RAM, which works but is far slower. Long contexts (32K+) need more memory than these figures.
One short email a week: what got cheaper, what's back in stock, and which new open models your machine can run. Unsubscribe anytime.