RTX 4090In stock
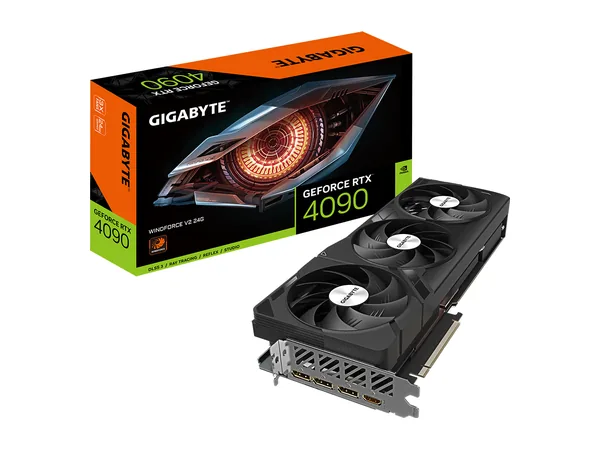
Gigabyte GeForce RTX 4090 Windforce V2
24GB card
$4,899at Newegg
1,008 GB/s (card only, needs a host PC)
Check priceMemory guide · 24GB VRAM
7 of the 16 open models we track fit in 24GB VRAM without spilling into system RAM, the biggest being Gemma 4 31B. Speeds range from about 43 to 214 tokens/sec depending on the model and machine. Prices & stock checked 2026-10-23. Prices change daily and some retailers block our checker, so always confirm on the store page.
| Model | Needs at 4-bit | Gigabyte GeForce RTX 4090 Windforce V21,008 GB/s |
|---|---|---|
| Qwen3.5 9Bdense · 9B active · chat, small agents | ~7 GB | Fits~80 tok/sQ8_0 |
| Gemma 4 12Bdense · 12B active · chat, vision | ~9 GB | Fits~62 tok/sQ8_0 |
| GPT-OSS 20BMoE · 3.6B active · reasoning, tools | ~13 GB | Fits~209 tok/sMXFP4 (native) |
| Gemma 4 26B-A4BMoE · 3.8B active · fast general chat | ~18 GB | Fits~190 tok/sQ4_K_M |
| Qwen3.8 27Bdense · 27B active · coding, vision, general | ~19 GB | Fits~49 tok/sQ4_K_M |
| GLM-4.7-Flash 30B-A3BMoE · 3B active · coding agents | ~21 GB | Tight fit~214 tok/sQ4_K_M |
| Gemma 4 31Bdense · 31B active · general, vision | ~21 GB | Tight fit~43 tok/sQ4_K_M |
Each column shows the quant we'd use (8-bit when it fits comfortably and still runs 10+ tok/s, otherwise 4-bit) and the estimated decode speed for one user at ~8K context. How we estimate
Just out of reach: Qwen3.6 35B-A3B (~24 GB at 4-bit), Llama 3.3 70B (~46 GB at 4-bit), Qwen3-Next 80B-A3B (~52 GB at 4-bit).
24GB card
1,008 GB/s (card only, needs a host PC)
Check priceAlso 24GB, but unified memory: Mac mini M5 Pro. It has a different usable share and bandwidth, so check its own page.
Of the models we track, Gemma 4 31B is the largest that fits fully in 24GB VRAM (Q4_K_M, about 21 GB including runtime and ~8K context).
Of the machines we track, the Gigabyte GeForce RTX 4090 Windforce V2 at $4,899 (Newegg, checked 2026-10-23) (card only, needs a host PC).
Not fully in memory. At 4-bit it needs about 46 GB including runtime and ~8K context.
Memory needed = weights + 1.5 GB + 5% of weights. Decode speed ≈ 1 ÷ (active weights in GB ÷ (efficiency × memory bandwidth) + a small fixed per-token overhead), with efficiency and overhead fitted per platform to 43 public llama.cpp/MLX benchmarks (median error about 5%). They're estimates, not benchmarks.
One short email a week: what got cheaper, what's back in stock, and which new open models your machine can run. Unsubscribe anytime.