RTX 4090In stock
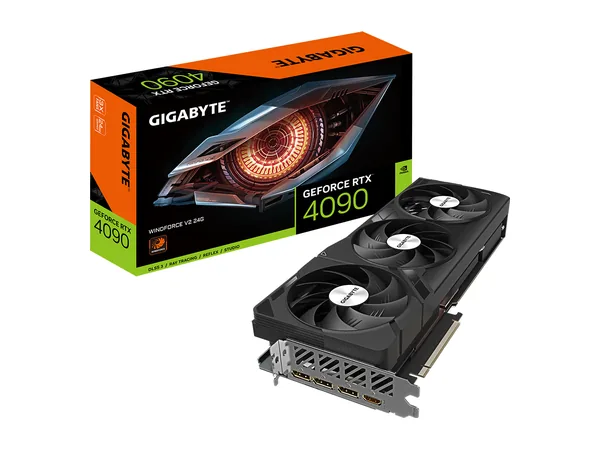
Gigabyte GeForce RTX 4090 Windforce V2
24GB card
$4,899at Newegg
24 GB VRAM · 1,008 GB/s
GPU price is card only: you still need a host PC.
Check priceGPU guide
For local LLMs, a GPU's VRAM decides which models fit and its memory bandwidth decides how fast they run. We track 3 cards. The PNY NVIDIA RTX PRO 6000 Blackwell fits the biggest models (96 GB) and is also the cheapest per GB of VRAM right now ($186.45/GB). Card prices exclude the host PC. Prices & stock checked 2026-10-24. Prices change daily and some retailers block our checker, so always confirm on the store page.
| Card | Price (card only) | VRAM | Usable for models | Bandwidth | $ / GB |
|---|---|---|---|---|---|
| Gigabyte GeForce RTX 4090 Windforce V2 | $4,899 | 24 GB | ~22 GB | 1,008 GB/s | $204.12 |
| NVIDIA GeForce RTX 5090 Founders Edition | $8,500 | 32 GB | ~30 GB | 1,792 GB/s | $265.62 |
| PNY NVIDIA RTX PRO 6000 Blackwell | $17,899 | 96 GB | ~89 GB | 1,792 GB/s | $186.45 |
| Model | RTX 4090 Windforce V224 GB · $4,899 | RTX 5090 Founders Edition32 GB · $8,500 | RTX PRO 6000 Blackwell96 GB · $17,899 |
|---|---|---|---|
| Qwen3.5 9B~7 GB at 4-bit | Fits~133 tok/s | Fits~214 tok/s | Fits~214 tok/s |
| GPT-OSS 20B~13 GB at 4-bit | Fits~209 tok/s | Fits~264 tok/s | Fits~264 tok/s |
| Qwen3.6 35B-A3B~24 GB at 4-bit | Won't fit | Fits~269 tok/s | Fits~269 tok/s |
| Qwen3.8 27B~19 GB at 4-bit | Fits~49 tok/s | Fits~83 tok/s | Fits~83 tok/s |
| Gemma 4 31B~21 GB at 4-bit | Tight fit~43 tok/s | Fits~73 tok/s | Fits~73 tok/s |
| Llama 3.3 70B~46 GB at 4-bit | Won't fit | Won't fit | Fits~34 tok/s |
| GPT-OSS 120B~67 GB at 4-bit | Won't fit | Won't fit | Fits~231 tok/s |
| Qwen3.5 122B-A10B~79 GB at 4-bit | Won't fit | Won't fit | Fits~152 tok/s |
Estimated single-user decode at ~8K context, model fully in VRAM (no offload to system RAM). How we estimate
| Hardware | Model / run | Measured tok/s | Our formula | Source |
|---|---|---|---|---|
| RTX PRO 60001,792 GB/s | Llama-2 7B Q4_0llama.cpp tg128 | 274.2 | 280.4 | source |
| RTX PRO 60001,792 GB/s | Llama 3.3 70B Q4_K_Mllama.cpp tg128 | 34.0 | 33.8 | source |
| RTX PRO 60001,792 GB/s | gpt-oss-120b MXFP4llama.cpp tg128 | 196.3 | 231.4 | source |
| RTX PRO 60001,792 GB/s | gpt-oss-20b MXFP4llama.cpp tg128 | 286.9 | 264.1 | source |
| RTX 50901,792 GB/s | Llama-2 7B Q4_0llama.cpp tg128 | 290.0 | 280.4 | source |
| RTX 50901,792 GB/s | Qwen3.6-27B Q4_K_Mllama.cpp tg128 | 77.1 | 81.3 | source |
| RTX 50901,792 GB/s | Qwen3.6-35B-A3B UD-Q4_K_Mllama.cpp tg128 | 271.0 | 268.6 | source |
| RTX 50901,792 GB/s | gpt-oss-20b MXFP4llama.cpp tg128 | 282.5 | 264.1 | source |
| RTX 40901,008 GB/s | Llama-2 7B Q4_0llama.cpp tg128 | 186.2 | 179.8 | source |
| RTX 40901,008 GB/s | Qwen3 32B Q4_K_Mllama.cpp tg128 | 42.0 | 40.4 | source |
| RTX 40901,008 GB/s | gpt-oss-20b MXFP4llama.cpp tg128 | 222.0 | 208.9 | source |
| RTX 40901,008 GB/s | Qwen3 30B-A3B Q4_K_Mllama.cpp tg128 (fusion off) | 198.4 | 204.4 | source |
| RTX PRO 60001,792 GB/s | gpt-oss-120b MXFP4llama.cpp 4K ctx (newer build) | 221.3 | 231.4 | source |
| RTX 50901,792 GB/s | Qwen3 30B-A3B Q4_K_Mllama.cpp + GGML_CUDA_GRAPH_OPT=1 | 352.1 | 260.1 | source |
| RTX 50901,792 GB/s | gpt-oss-20b MXFP4llama.cpp + GGML_CUDA_GRAPH_OPT=1 | 419.1 | 264.1 | source |
Public llama.cpp results we calibrate against. Newer builds and CUDA graph options can be faster. Full list: our estimates vs 52 real benchmarks.
24GB card
24 GB VRAM · 1,008 GB/s
GPU price is card only: you still need a host PC.
Check price32GB card
32 GB VRAM · 1,792 GB/s
GPU price is card only: you still need a host PC.
Check price96GB card
96 GB VRAM · 1,792 GB/s
GPU price is card only: you still need a host PC.
Check priceIt depends on model size. Of the cards we track, the PNY NVIDIA RTX PRO 6000 Blackwell has the most VRAM (96 GB), so it runs 70B dense and 120B-class MoE models on one card. For 20–35B models, a 24–32 GB card is enough and much cheaper.
About 13 GB for GPT-OSS 20B, 19 GB for a 27B model and 46 GB for Llama 3.3 70B at 4-bit, including ~8K context. Discrete cards leave ~93% of VRAM usable.
The RTX 5090 has 32 GB and 1,792 GB/s versus 24 GB and 1,008 GB/s on the 4090, so it fits bigger models and decodes about 1.3–1.7× faster on models both can hold (our estimate). Right now the 5090 we track is $8,500 and the 4090 is $4,899 (card only).
GPUs are much faster on models that fit in VRAM and lead on prompt processing. Unified-memory boxes are slower per token but fit far bigger models for the money, since a 96–128 GB GPU costs much more than a 128 GB mini PC.
One short email a week: what got cheaper, what's back in stock, and which new open models your machine can run. Unsubscribe anytime.