Head to head · NVIDIA vs NVIDIA
DGX Spark vs RTX 5090 for local LLMs
They solve different problems. The RTX 5090 has 32 GB at 1,792 GB/s: about 6.6× the Spark's bandwidth, so models that fit run roughly 3.2–6.6× faster (our estimate). On the one model both have public runs for, gpt-oss-20b, the Spark measured 83 tok/s and the 5090 282 tok/s. The DGX Spark has 128 GB (~109 GB usable) at 273 GB/s, so it holds 6 models we track that a single 5090 can't, up to Qwen3.5 122B-A10B. Prices & stock checked 2026-10-24. Prices change daily and some retailers block our checker, so always confirm on the store page.
Specs that matter
| DGX Spark / GB10 | RTX 5090 | |
|---|---|---|
| Price | $5,859cheapest GB10 box, complete system | $8,500card only, needs a host PC |
| Memory | 128 GB unified (~109 GB usable) | 32 GB VRAM (~30 GB usable) |
| Bandwidth | 273 GB/s | 1,792 GB/s |
| Models that fit (4-bit) | 14 of 16 | 8 of 16 |
Model by model (4-bit)
| Model | DGX Spark | RTX 5090 |
|---|---|---|
| Qwen3.5 9B~7 GB at 4-bit | Fits~39 tok/s | Fits~214 tok/s |
| Gemma 4 12B~9 GB at 4-bit | Fits~29 tok/s | Fits~170 tok/s |
| GPT-OSS 20B~13 GB at 4-bit | Fits~80 tok/s | Fits~264 tok/s |
| Gemma 4 26B-A4B~18 GB at 4-bit | Fits~70 tok/s | Fits~247 tok/s |
| Qwen3.8 27B~19 GB at 4-bit | Fits~13 tok/s | Fits~83 tok/s |
| GLM-4.7-Flash 30B-A3B~21 GB at 4-bit | Fits~83 tok/s | Fits~269 tok/s |
| Gemma 4 31B~21 GB at 4-bit | Fits~11 tok/s | Fits~73 tok/s |
| Qwen3.6 35B-A3B~24 GB at 4-bit | Fits~83 tok/s | Fits~269 tok/s |
| Llama 3.3 70B~46 GB at 4-bit | Fits~5 tok/s | Won't fit |
| Qwen3-Next 80B-A3B~52 GB at 4-bit | Fits~83 tok/s | Won't fit |
| Llama 4 Scout 109B-A17B~71 GB at 4-bit | Fits~19 tok/s | Won't fit |
| GPT-OSS 120B~67 GB at 4-bit | Fits~61 tok/s | Won't fit |
| Nemotron 3 Super 120B-A12B~78 GB at 4-bit | Fits~26 tok/s | Won't fit |
| Qwen3.5 122B-A10B~79 GB at 4-bit | Fits~31 tok/s | Won't fit |
Estimated single-user decode at ~8K context; 5090 figures assume the model is fully in VRAM. How we estimate
Measured runs vs our formula
| Hardware | Model / run | Measured tok/s | Our formula | Source |
|---|---|---|---|---|
| DGX Spark273 GB/s | Qwen2.5-Coder 7B Q8_0llama.cpp tg32 | 29.4 | 26.0 | source |
| DGX Spark273 GB/s | Gemma 3 4B Q4_0llama.cpp tg32 | 81.0 | 83.4 | source |
| DGX Spark273 GB/s | gpt-oss-120b MXFP4llama.cpp tg32 | 58.7 | 61.4 | source |
| DGX Spark273 GB/s | gpt-oss-20b MXFP4llama.cpp tg32 | 83.4 | 80.0 | source |
| DGX Spark273 GB/s | Qwen3-Coder 30B-A3B Q8_0llama.cpp tg32 | 61.1 | 49.8 | source |
| DGX Spark273 GB/s | GLM-4.7-Flash Q8_0llama.cpp tg32 | 48.7 | 53.9 | source |
| DGX Spark273 GB/s | Qwen3.5-122B-A10B Q5_K_Sllama.cpp tg128 | 23.0 | 27.7 | source |
| Dell Pro Max GB10273 GB/s | Llama 3.1 70B Q4_K_MOllama (Geerling) | 4.7 | 4.9 | source |
| RTX 50901,792 GB/s | Llama-2 7B Q4_0llama.cpp tg128 | 290.0 | 280.4 | source |
| RTX 50901,792 GB/s | Qwen3.6-27B Q4_K_Mllama.cpp tg128 | 77.1 | 81.3 | source |
| RTX 50901,792 GB/s | Qwen3.6-35B-A3B UD-Q4_K_Mllama.cpp tg128 | 271.0 | 268.6 | source |
| RTX 50901,792 GB/s | gpt-oss-20b MXFP4llama.cpp tg128 | 282.5 | 264.1 | source |
| RTX 50901,792 GB/s | Qwen3 30B-A3B Q4_K_Mllama.cpp + GGML_CUDA_GRAPH_OPT=1 | 352.1 | 260.1 | source |
| RTX 50901,792 GB/s | gpt-oss-20b MXFP4llama.cpp + GGML_CUDA_GRAPH_OPT=1 | 419.1 | 264.1 | source |
Public single-user decode results we calibrate against. Runs differ in build and settings, so compare like with like.
Prices
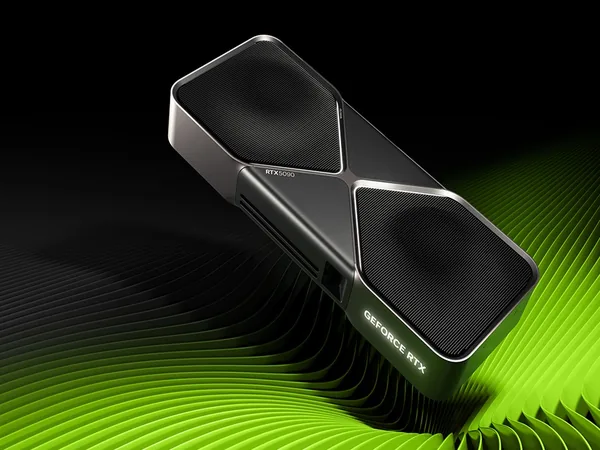
NVIDIA GeForce RTX 5090 Founders Edition
32GB card
32 GB VRAM · 1,792 GB/s
Card only: you still need a host PC.
Check priceFAQ
Is DGX Spark faster than an RTX 5090?
No. On models that fit in 32 GB, the 5090 is about 3.2–6.6× faster by our estimate, because it has 1,792 GB/s versus 273 GB/s. On the one model both have public runs for, gpt-oss-20b, the Spark measured 83 tok/s and the 5090 282 tok/s.
Why buy a DGX Spark instead of a 5090?
Memory. The Spark's ~109 GB usable holds models like GPT-OSS 120B, Nemotron 3 Super 120B-A12B, Qwen3.5 122B-A10B that won't fit in a single 5090's ~30 GB, and it's a complete computer.
What do they cost?
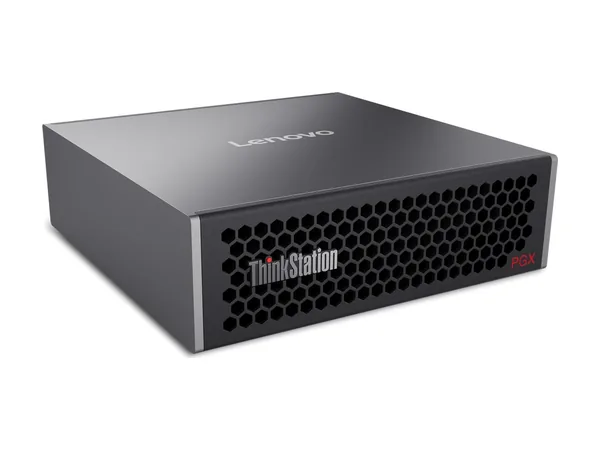
The cheapest GB10 box we track is $5,859 (Lenovo ThinkStation PGX), a complete system. The RTX 5090 Founders Edition is $8,500 for the card only; you still need a host PC, which we don't price.
Can the RTX 5090 run Llama 70B?
Not fully in VRAM: it needs ~46 GB at 4-bit. The Spark fits it but runs it at ~5 tok/s.
Which is better for coding models like Qwen3.6 35B-A3B?
If it fits, the 5090: we estimate ~269 tok/s vs ~83 on the Spark at 4-bit.