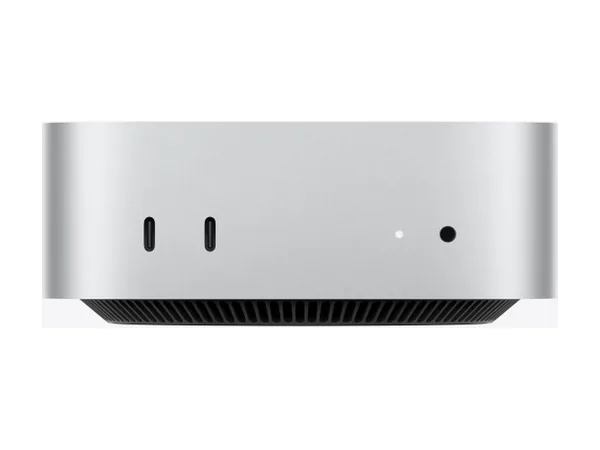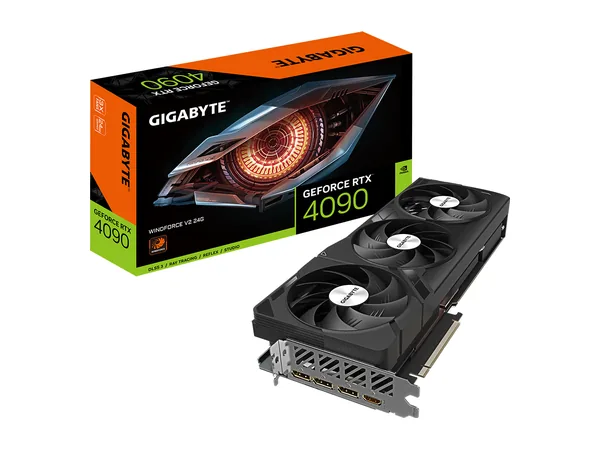
RTX 4090In stock
Gigabyte GeForce RTX 4090 Windforce V2
24GB card
$4,899at Newegg
24 GB · 1,008 GB/s (card only, needs a host PC)
Check pricePicks · 24GB VRAM
On a 24 GB GPU, 9 of the 22 open models we track fit at 4-bit or better. The best coding pick is Qwen3 30B-A3B (~204 tok/s on an RTX 4090, our estimate); 70B models (~46 GB) don’t fit. Picks by use case are below.
| Model | Best quant that fits | RTX 4090 tok/s (est.) | Mac mini M5 Pro |
|---|---|---|---|
| Qwen3.5 9Bchat, small agents | Q8_0~12 GB | ~80 | Fits~48 tok/s |
| Gemma 4 12Bchat, vision | Q8_0~15 GB | ~62 | Fits~36 tok/s |
| GPT-OSS 20Breasoning, tools | MXFP4 (native)~13 GB | ~209 | Fits~82 tok/s |
| Gemma 4 26B-A4Bfast general chat | Q4_K_M~18 GB | ~190 | Won't fit |
| Qwen3.8 27Bcoding, vision, general | Q4_K_M~19 GB | ~49 | Won't fit |
| Gemma 3 27Bgeneral, vision | Q4_K_M~19 GB | ~48 | Won't fit |
| GLM-4.7-Flash 30B-A3Bcoding agents | Q4_K_M~21 GB | ~214 | Won't fit |
| Qwen3 30B-A3Bfast chat & coding | Q4_K_M~21 GB | ~204 | Won't fit |
| Gemma 4 31Bgeneral, vision | Q4_K_M~21 GB | ~43 | Won't fit |
24 GB card with ~93% usable (~22.3 GB); 8-bit when it fits with headroom, otherwise 4-bit. Estimated single-user decode at ~8K context; GPU-card figures assume the model is fully in VRAM. How we estimate
Qwen3 32B (~22.4 GB), DeepSeek R1 Distill Qwen 32B (~22.4 GB), Qwen3.6 35B-A3B (~23.8 GB). These need a 32–48 GB card, two GPUs, or a unified-memory machine.
Public single-user decode results we calibrate against. Runs differ in build and settings, so compare like with like.
| Hardware | Model / run | Measured tok/s | Our formula | Source |
|---|---|---|---|---|
| RTX 40901,008 GB/s | Llama-2 7B Q4_0llama.cpp tg128 | 186.2 | 179.8 | source |
| RTX 40901,008 GB/s | Qwen3 32B Q4_K_Mllama.cpp tg128 | 42.0 | 40.4 | source |
| RTX 40901,008 GB/s | gpt-oss-20b MXFP4llama.cpp tg128 | 222.0 | 208.9 | source |
| RTX 40901,008 GB/s | Qwen3 30B-A3B Q4_K_Mllama.cpp tg128 (fusion off) | 198.4 | 204.4 | source |
24GB card
24 GB · 1,008 GB/s (card only, needs a host PC)
Check price15-core CPU / 16-core GPU, 24GB
24 GB · 307 GB/s
Check priceBy use case: coding: Qwen3 30B-A3B; reasoning: GPT-OSS 20B; vision: Gemma 4 31B; fast chat: GLM-4.7-Flash 30B-A3B. All fit at 4-bit or better with ~8K context.
Not fully in VRAM: Llama 3.3 70B needs ~46 GB at 4-bit. Ollama can offload layers to system RAM, but it slows down a lot.
No: it needs ~23.8 GB at 4-bit vs ~22.3 GB usable.
Both have 24 GB, so the same models fit. We don’t track or price the 3090 yet, so we don’t publish speed numbers for it.
The 4090 card ($4,899, needs a host PC) has 1,008 GB/s vs 307 GB/s and ~22 GB usable vs ~17 GB on the Mac mini M5 Pro ($1,699, a complete computer), so it fits more and runs faster.
One short email a week: what got cheaper, what's back in stock, and which new open models your machine can run. Unsubscribe anytime.